Introduction
Global internet users launch banking apps, e-commerce stores, and communication hubs constantly. A frozen checkout screen drives dissatisfied consumers away to rival platforms within seconds. Site Reliability Engineering combines smart coding techniques with computer operations to safeguard critical services. This practice builds unbreakable electronic paths that keep traffic flowing freely day and night. Tech professionals visit SRESchool.com to master production engineering skills through interactive labs and clear guidance. The platform prepares ambitious engineers to defend complex computing systems against sudden failures.
What Is SRESchool.com?
Reliable machinery finishes its assigned job without giving up midway through the task. Picture a sturdy bicycle that pedals forward smoothly every morning without popping a chain. SRESchool.com teaches technical teams how to bring that same rock-solid trust to software. Specialists track real operational numbers, observe active server clusters, build defensive scripts, and isolate hidden bugs. They examine tiny failures early so systems survive gigantic traffic surges. This clear habit ensures smooth digital experiences for millions of everyday customers.
Why Does SRESchool.com Matter?
Global commerce runs across deep software pipelines, web databases, computer clouds, and fiber-optic networks. A single misplaced symbol in a script can knock an entire payment gateway offline. SRESchool.com trains engineers to identify silent infrastructure defects before real customers suffer. These quick diagnostics guide developers straight to the root error for rapid patches. Spotting defects fast saves enterprises enormous sums in emergency repair fees. Daily reliability habits make complex computer systems safe, fast, and durable.
What Does an SRESchool.com Team Do?
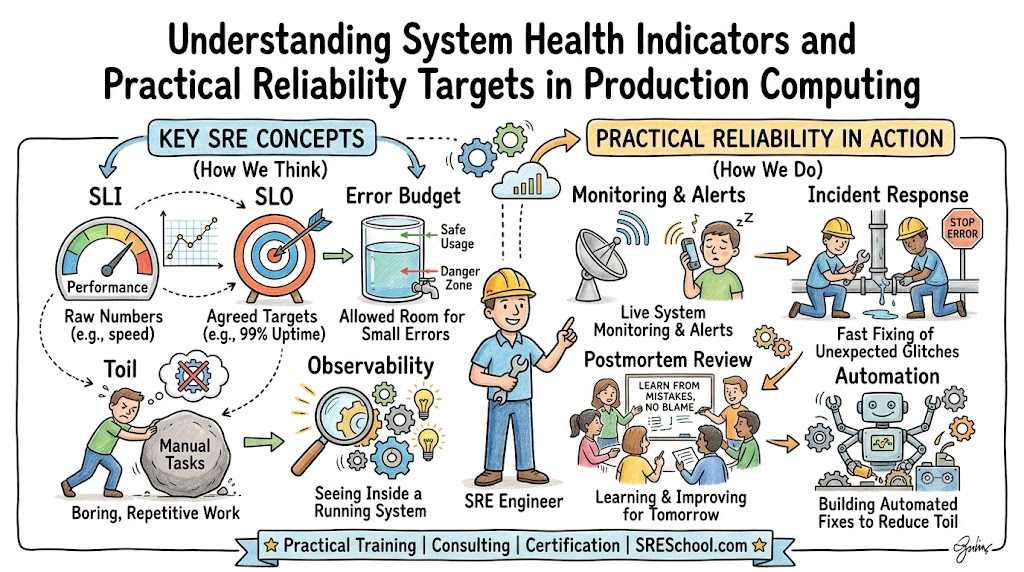
A dedicated crew takes care of essential jobs to safeguard critical computers day and night. They mount colorful tracking screens to observe live network traffic like radar operators. Clear threshold signals alert workers only when serious technical damage threatens user access. The team conducts rapid emergency repairs to return frozen services back to health. They create custom software robots to take over tedious, time-consuming administrative chores. Careful planning helps them buy computer hardware ahead of big holiday crowds. The group also writes postmortems to study crashes calmly without pointing fingers at colleagues.
Key SRE Terms Made Easy
Reliability pros use short terms to describe daily software health checks. A service level indicator calculates exact response times or up periods for a service. A service level objective states a firm promise for overall health, like ninety-nine percent uptime. An error budget displays the brief downtime an application can burn without angering users. Toil describes boring manual jobs that quick software scripts could easily finish instead. Observability lets engineers view inner program flows to spot hidden bottlenecks fast. When alerts fire, an on-call engineer fixes the active system incident right away.
| SRE Term | Simple Meaning | Example |
| SLI | A direct measurement of app speed | Reading server response times in milliseconds |
| SLO | A target goal for overall stability | Keeping an online store alive 99.5% of the year |
| Error Budget | The allowed margin for system hiccups | Spending thirty minutes on software updates |
| Toil | Boring manual computer chores | Typing the same restart commands every sunrise |
| Observability | Seeing deep inside running code | Following a lost user purchase across microservices |
| On-Call | Standing by to resolve emergencies | Fixing a frozen shopping cart at midnight |
| Incident | An unplanned disruption of service | Resolving a broken database after a bad patch |
What Is SRE Training?
Comprehensive SRE Training guides novices through core methods for keeping computer networks functional. Learners study infrastructure metrics, cloud clusters, auto-healing programs, and rapid incident recovery. They discover smart ways to cut down on toil so creators can build cool products. Hands-on laboratory work lets students fix realistic simulated system crashes on private test servers. Memorizing paper facts is fine, but true server experiments spark actual technical capability. SRESchool.com guides eager learners along clear steps so they master critical engineering skills smoothly. Rich practice helps ambitious students earn rewarding technology positions.
What Is SRE Certification?
A recognized SRE Certification validates your skill in running large commercial software operations safely. A Certified Site Reliability Engineer understands how to track performance data, fix outages, and code. This credential tells hiring directors that you grasp recovery tactics and system metrics. Yet a paper certificate alone will never transform you into a senior engineer overnight. Modern tech companies care far more about solved problems and verified laboratory projects. You must combine certified test knowledge with true hands-on server experiments to shine. That balanced effort opens fantastic engineering career paths worldwide.
What Is a Site Reliability Engineering Course?
An organized Site Reliability Engineering Course moves learners through a clear educational ladder. First, you master base operating system basics and simple server health indicators. Next, you set up real reliability goals and trace active software errors. Then, you practice emergency incident drills and write clever computer automation scripts. After that, you study cloud networks and balance release speeds with error budgets. Finally, you jump into realistic labs that feel like huge enterprise platforms. This structured pathway helps developers and system admins step into senior reliability roles with confidence.
SRE Tools Made Simple
Engineers employ targeted software packages to observe and fix enormous software networks. Tracking utilities like Prometheus collect key numbers on CPU heat and storage use. Visual interfaces like Grafana render clean graphs so people can spot trends immediately. Tracing utilities like OpenTelemetry monitor an individual mouse click through complex cloud pathways. Warning engines page the right engineer when memory pools start to fill up. Cloud platforms and code automation tools spin up fresh machines without human hands. These smart helpers free up engineers to design safer and faster systems.
| Learning Area | What Learners Can Practice |
| System Monitoring | Configuring Prometheus to read live server telemetry |
| Live Dashboards | Designing visual Grafana screens for user traffic |
| Software Tracing | Tracing slow checkout buttons with OpenTelemetry |
| Automated Tasks | Writing short scripts to clean up old database logs |
| Incident Response | Handling practice outage drills during team exercises |
| Cloud Reliability | Moving web traffic between healthy server regions |
Real-Life Scenarios
- A retail portal slows down under massive holiday traffic, so an automated script provisions eight additional virtual servers immediately.
- A faulty code release breaks login fields, but safety gates freeze future deployments until developers resolve the defect.
- A primary database runs short on disk memory, so an alert notifies the on-call engineer to expand disk space within minutes.
- A network fiber cable snaps in an overseas facility, so internet routers shift traffic to alternate zones without dropping user sessions.
What Is SRE Consulting?
Growing companies often bring in expert SRE Consulting firms to diagnose unstable cloud networks. These seasoned experts inspect fragile failure points and craft sensible availability standards. They repair noisy alert systems so engineers sleep through harmless warnings. Advisors also show in-house teams how to script routine operational chores and manage bad outages. They hand over an actionable roadmap that speeds up company systems dramatically. This expert direction shields client revenue, maintains user goodwill, and cuts expensive infrastructure waste.
What Is SRE as a Service?
Smaller businesses often adopt SRE as a Service when they lack internal reliability specialists. This flexible arrangement gives firms instant access to veteran operational talent on demand. Outside professionals oversee cloud platforms, evaluate system capacity, and resolve sudden disruptions. They also configure automated protection rules and run system tune-ups. However, corporate managers must specify exact technical goals before signing external vendor contracts. Clear boundaries keep outside contractors focused on high-priority platforms without squandering resources. This assistance ensures vital applications stay up constantly.
What Is Corporate SRE Training?
Forward-thinking companies invest in Corporate SRE Training to align all technical groups under one mindset. This tailored curriculum gives programmers, cloud architects, and system administrators a unified reliability language. Staff members learn how to evaluate code for resilience before shipping it to clients. They rehearse simulated disaster scenarios together so live emergencies do not cause widespread panic. Everyone discovers how to set balanced reliability goals and eliminate soul-crushing manual chores. Customized lessons focus on the exact tools and servers the company uses daily. This group learning turns ordinary tech teams into powerhouse engineering units.
Common Mistakes to Avoid When Choosing Delhi Events
- Ignoring core business objectives while setting impossible performance benchmarks for tiny systems.
- Waking engineers in the middle of the night for trivial warnings that resolve themselves.
- Reprimanding honest staff after mistakes occur rather than fixing broken deployment pipelines.
- Squandering entire workdays on manual procedures instead of coding clever automation routines.
- Skipping thorough post-incident documentation after a nasty production outage rocks user accounts.
- Concealing service outage updates from clients instead of posting transparent operational reports.
- Collecting piles of unhelpful system data while ignoring actual user satisfaction.
- Pushing untested code to live servers without checking remaining error budget levels first.
How SRESchool.com Can Help
SRESchool.com provides a comprehensive home for growing technical staff and modern enterprises alike. Students explore rich SRE Tutorial resources, structured coursework, and hands-on SRE Tools exercises. The platform delivers SRE Training tracks that prepare you for an SRE Certification exam. Engineering departments can also schedule Corporate SRE Training around their exact cloud stack. Organizations needing senior guidance can lean on SRE Consulting or SRE as a Service. The platform shows you how to run resilient, scalable, and observable computer systems. It gives you the practical knowledge to solve real production challenges with total confidence.
Frequently Asked Questions
1. What core problem does Site Reliability Engineering solve?
Site Reliability Engineering keeps online services from falling apart during peak consumer demand. It uses software engineering methods to manage traditional, messy infrastructure issues. Teams use automation, performance indicators, and smart alert rules to build dependable services. This modern practice shields organizations from costly system downtime and unhappy customers.
2. Can self-taught beginners grasp SRE concepts easily?
Yes, motivated beginners can master Site Reliability Engineering through steady practice and curiosity. Knowing fundamental computer logic and simple Python commands speeds up progress noticeably. Novices should master basic operating system commands, cloud resources, and automation first. Real-world laboratory drills build true operational competence step by step.
3. Does SRE work against agile DevOps practices?
No, SRE reinforces DevOps culture by providing concrete mathematical rules for system health. DevOps champions fast software delivery, while SRE supplies the guardrails that prevent crashes. Teams use error budgets and service level targets to govern release speeds. Both concepts join forces to deliver high-quality software safely.
4. How does an engineering team pick a good SLO?
Teams build an SLO around realistic customer happiness rather than chasing impossible perfection. Developers and product managers agree on an acceptable uptime goal, like 99.5 percent. This clear number tells everyone when an application runs safely for paying visitors. It keeps teams from releasing risky updates too fast.
5. Why do businesses care about error budgets?
An error budget reveals the precise amount of downtime a service can suffer without pain. It brings harmony to the classic battle between rapid features and overall stability. When a team burns through its budget on bugs, feature launches stop instantly. This smart rule keeps engineers and executives on the same page.
6. Which basic programs should a newcomer try first?
Beginners should start with command-line Linux terminals and basic Python scripting. Soon after, they should try Prometheus for metric collection and Grafana for visual dashboards. Gaining experience on cloud hosts like AWS or Google Cloud also helps immensely. These foundational instruments power reliability tasks across top technology enterprises.
7. Why should engineers work hard to eliminate toil?
Toil consists of repetitive, boring manual chores that create zero enduring value for businesses. Writing short computer scripts lets automated workers complete basic tasks like system reboots. Removing this busywork frees engineers to craft innovative products and design safer architectures. Teams achieve far more meaningful outcomes while preventing burnout.
8. Who benefits from holding a blameless postmortem meeting?
The entire organization benefits from exploring a serious outage without pointing fingers at colleagues. Coworkers explain technical breakdowns honestly when they do not fear unfair punishments. The team focuses on strengthening system barriers, test pipelines, and real-time monitoring. This constructive habit prevents identical glitches from disrupting production later.
9. When should an enterprise hire external reliability advisors?
Companies hire outside consultants when their core systems suffer frequent crashes or sluggish performance. Seasoned advisors examine fragile cloud setups, find hidden bottlenecks, and design sound performance targets. They also teach existing employees better incident recovery habits and automation tricks. This guidance helps companies stabilize platforms rapidly.
10. Where can students find top-tier reliability programs?
Top-tier programs emphasize real laboratory challenges over passive slide reading. Look for courses that teach active observability, emergency triage, and cloud networking clearly. Strong courses also provide helpful mentor feedback, updated learning materials, and practical projects. SRESchool.com delivers these practical exercises to help learners succeed.
11. Does earning an industry certificate guarantee career success?
Completing an industry certification proves that you take your professional engineering path seriously. It helps your resume catch the attention of recruiters and hiring managers. Even so, you must back up your certificate with working laboratory experience. Building, testing, and fixing real servers demonstrates genuine technical value.
12. How does on-demand SRE support help young startups?
Young startups often lack the funding to maintain full-time reliability departments internally. On-demand SRE services supply access to seasoned reliability veterans whenever tricky problems emerge. These professionals set up monitoring pipelines, secure cloud networks, and resolve server outages. Startups receive enterprise-grade stability without spending huge budgets.
Conclusion
Reliable software guarantees sustained business growth in our connected global economy. Site Reliability Engineering brings together automation, active monitoring, and balanced health targets to stop outages. Skilled specialists replace tedious manual chores with code and study past failures without blame. Ambitious individuals can learn these valuable techniques through hands-on labs, structured coursework, and open tutorials. Growing companies can also tap outside advisory groups, staff training sessions, and managed reliability help. Platforms like SRESchool.com help engineers and business teams learn, grow, and build dependable systems together.
