Introduction
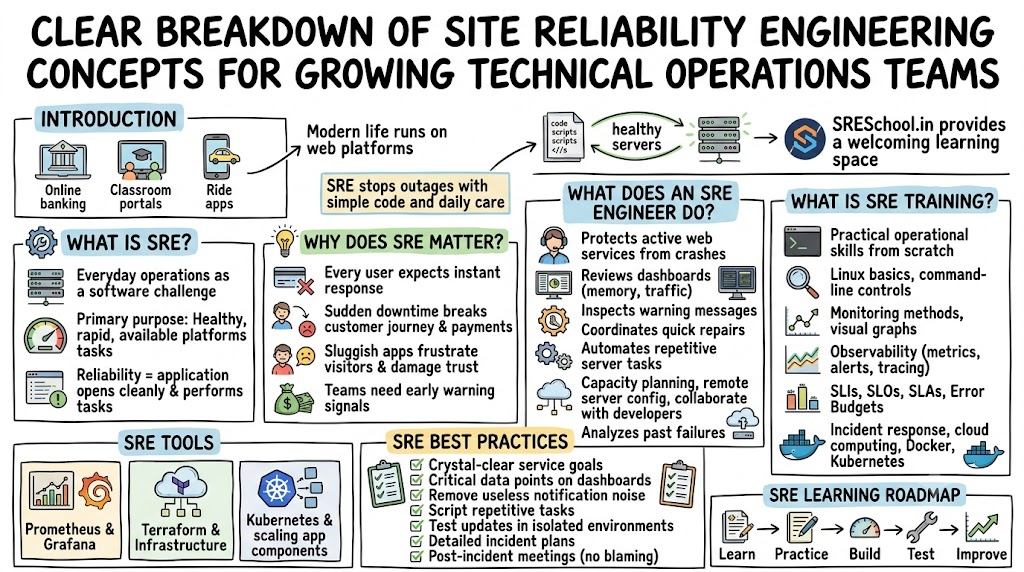
Modern society runs on vast webs of digital tools every single hour. People expect quick, uninterrupted service when they open their favorite work applications or banking portals. System failures cause immediate frustration, stall business progress, and damage user confidence. Forward-thinking teams tackle these challenges by writing resilient code that directs live infrastructure operations. This discipline builds rock-solid production environments through continuous automation and proactive system health tracking. Throughout this guide, you will explore core metrics, incident resolution tactics, and practical deployment tools. Each chapter translates sophisticated operations concepts into clear, simple ideas that anyone can master. SRESchool.in provides a welcoming learning space where students develop these valuable technological abilities. You will gain the exact knowledge required to maintain dependable, lightning-fast digital experiences.
What Is Site Reliability Engineering?
Site Reliability Engineering treats computer operations as a pure software problem. Teams write custom programs to run and protect their live systems. High reliability means your application works without unexpected crashes or slowdowns. System uptime measures the exact time a service remains available to users. Fast performance ensures that pages open instantly whenever someone taps a screen. Stability protects your digital network against sudden surges in user traffic. Teams embrace automation by writing tiny scripts that execute routine administrative chores. Automation replaces repetitive manual labor with quick computer logic. Monitoring tools continuously watch servers and warn staff before users notice any damage.
Why Does SRE Matter?
Online shoppers demand flawless, responsive interactions whenever they browse an e-commerce platform. Severe downtime paralyzes checkout systems and leaves buyers searching for alternatives. Slow page responses drive prospective clients straight to rival brands in seconds. Catastrophic server disruptions erase millions of dollars in transaction fees and corporate revenue. Frequent platform outages also erode long-term customer trust and ruin professional reputations. Practicing reliability engineering lets teams identify hidden code defects before they cause harm. Engineers uncover the root causes of major errors to stop repeat failures. These proactive habits safeguard corporate income and keep everyday users confident and satisfied.
What Does an SRE Engineer Do?
An SRE Engineer defends production infrastructure against unexpected crashes and performance drops. Daily duties include reviewing telemetry dashboards to catch resource bottlenecks before servers stall. When hardware disks fill up, these professionals respond to real-time notification alerts. They take charge during sudden service disruptions and coordinate rapid recovery actions. Engineers also design scripts that automate routine administrative chores like clearing temporary caches. They calculate future computing needs so servers can absorb massive seasonal traffic rushes. Additionally, they collaborate with software developers to review application updates before public launches. For instance, when payment flows freeze during an event, the engineer traces blocked network calls and restores transactions.
What Is SRE Training?
Comprehensive SRE Training equips learners with the hands-on skills needed to run massive production networks. Students begin with Linux fundamentals, since open-source kernels power the modern internet. Next, they explore observability tools to inspect software performance behind the scenes. A Service Level Indicator tracks actual performance, such as response latency during peak hours. A Service Level Objective sets an internal operational target that teams strive to reach. A Service Level Agreement details formal performance commitments promised directly to enterprise customers. An error budget specifies how much temporary downtime an application can experience safely. Learners also practice incident response protocols to resolve outages under tight deadlines. Courses introduce container tools like Docker and Kubernetes so students can organize and deploy software efficiently.
Why Consider SRE Certification?
An SRE Certification provides a structured framework that guides your independent study. Pursuing a recognized credential helps you organize diverse technical topics logically. You follow an orderly syllabus and measure your progress across core operational concepts. However, written exams cannot replace authentic problem-solving experience on live computers. You must build real-world lab environments to sharpen your keyboard troubleshooting habits. Hands-on projects teach you how to remain calm during sudden technical emergencies. Pair your formal certificate with functional open-source projects to showcase your true abilities.
What Should an SRE Course Include?
A well-structured SRE Course leads students through progressive milestones of technical mastery.
| Stage Level | Subject Focus | Practical Takeaway |
| Level 1 | System Fundamentals | Grasp core availability principles and basic network rules |
| Level 2 | Linux Mastery | Execute administrative shell commands from the local terminal |
| Level 3 | Observability | Configure automated alerts for high CPU utilization |
| Level 4 | Service Level Objectives | Establish clear reliability targets based on user behavior |
| Level 5 | Outage Handling | Coordinate rapid team responses during catastrophic service failures |
| Level 6 | Cloud Architecture | Deploy scalable services across virtual cloud infrastructure |
| Level 7 | Scripted Automation | Write simple programs that restart dead application processes |
| Level 8 | Infrastructure as Code | Generate virtual computing resources using declarative text files |
| Level 9 | Resilient Projects | Build self-repairing web architectures inside container clusters |
| Level 10 | Production Operations | Maintain system stability under heavy user traffic simulations |
SRE Training in India
Technology hubs across India are migrating critical enterprise workloads into modern cloud platforms. Fast-growing software companies actively recruit specialists who understand continuous delivery and distributed infrastructure. Many Indian engineers manage worldwide services across multiple time zones every day. These engineers orchestrate complex architectures on popular platforms like Amazon Web Services and Google Cloud. They create modular scripts to launch fresh servers within minutes. Contemporary technology teams demand proven operational skills to manage enterprise systems without costly delays. SRESchool.in helps regional engineers develop these high-value, production-ready capabilities. Focused training empowers ambitious developers to secure rewarding roles in modern cloud engineering.
SRE Tools
Engineers use specialized software utilities to track, analyze, and manage modern applications.
| Tool Area | What It Does | Example Use |
| Monitoring | Collects system performance metrics | Prometheus tracks real-time RAM and processor load |
| Logging | Gathers raw event records | Elasticsearch stores application failure traces for analysis |
| Tracing | Follows individual user requests | Jaeger uncovers slow network hops during account logins |
| Alerting | Dispatches urgent notifications | PagerDuty pages the designated engineer during emergencies |
| Infrastructure | Provisions computing capacity | Terraform provisions virtual cloud servers through source code |
| Containers | Packages executable code packages | Kubernetes schedules and orchestrates container workloads |
SRE Best Practices
Reliable systems demand consistent engineering discipline and smart team habits every day. Organizations define unambiguous service standards so everyone understands target availability thresholds. Teams track meaningful telemetry data rather than drowning in useless noise. Engineers fine-tune alert thresholds so alarms sound only during real operational crises. Cutting down false alarms prevents responder burnout and keeps engineers sharp during emergencies. Teams automate routine maintenance chores to remove the risk of human typing mistakes. Developers test software releases thoroughly in isolated staging environments prior to production launches. Teams maintain accessible disaster recovery guides so responders can address failures quickly. Engineers hold blameless reviews after outages to locate systemic flaws and prevent future breakdowns.
Real-Life Scenarios
Operating live software environments presents unique challenges that test an engineering team’s readiness.
- Sudden Holiday Traffic Surge: A ticketing portal launches concert sales at midnight. Millions of fans refresh the web page simultaneously. The automated scaling mechanism notices the spike and spins up fifty new server nodes. The platform handles the massive rush smoothly without dropping a single customer transaction.
- Flawed Production Rollout: An engineer deploys an update containing a broken configuration file. System errors spike immediately on the live monitoring wall. The automated rollback tool catches the jump in failed requests and reinstates the prior version. Normal service returns in under ninety seconds without manual intervention.
- Storage Volume Exhaustion: An analytics cluster stops ingesting metrics because log files fill the entire local disk. The observability agent spots the diminishing free storage and alerts the operations desk. The engineer executes a cleanup script and increases volume capacity remotely. The reporting pipeline continues running without corrupting any analytical data.
Common SRE Mistakes to Avoid
Engineering squads frequently stumble into basic operational traps when scaling up their infrastructure.
- Alarm Flooding: Generating thousands of non-urgent warnings causes teams to ignore critical alarms. Fix: Eliminate trivial warnings and trigger alerts only on true user-facing issues.
- Manual Server Reboots: Restarting crashed virtual machines by hand creates unrecorded configuration drift and human errors. Fix: Implement automated watchdog scripts that restart dead processes automatically.
- Missing Service Targets: Running production systems without explicit availability targets leaves engineers guessing about priority fixes. Fix: Define clear target metrics in partnership with product managers.
- Skipping Post-Incident Analyses: Rushing past an outage without an investigation guarantees that identical issues will strike again. Fix: Conduct a blame-free postmortem after every critical service disruption.
- Testing on Live Customers: Releasing unverified updates straight into production risks massive service interruptions. Fix: Validate every code change inside realistic staging clusters first.
- Neglecting Growth Forecasts: Failing to track resource consumption causes unexpected capacity shortages during business expansions. Fix: Review historical resource trends monthly to order cloud capacity ahead of time.
- Blaming Individual Workers: Punishing individuals for human mistakes encourages workers to hide system defects. Fix: Focus post-incident analysis on fixing broken processes and improving automation.
- Unwritten Troubleshooting Steps: Storing recovery knowledge inside one person’s memory leaves teams helpless during midnight emergencies. Fix: Maintain clear, step-by-step recovery guides in a central knowledge base.
SRESchool.in Learning Support
Aspiring engineers can turn to SRESchool.in for comprehensive education in enterprise reliability techniques. The platform provides structured Site Reliability Engineering Training that stresses direct, hands-on terminal practice. Learners follow an extensive SRE Course designed to demystify complex distributed architectures. Serious students prepare for recognized Site Reliability Engineering Certification exams through thorough conceptual reviews. Clear SRE Tutorial materials break down challenging subjects like container clusters and automated rollback strategies. The curriculum highlights enterprise-grade SRE Tools used daily by leading infrastructure teams worldwide. Students also master time-tested SRE Best Practices to keep production networks available and secure. These resources prepare anyone seeking a long-term career as a professional SRE Engineer. The program delivers tailored SRE Training in India to support the next generation of cloud leaders.
SRE Learning Roadmap
Anyone can master modern cloud reliability by executing a straightforward five-stage learning plan.
- Learn: Study basic Linux file systems, shell commands, and foundational networking protocols like HTTP and DNS. Read the core principles behind system uptime and realistic failure budgets.
- Practice: Write short automation scripts using Python or Bash on your home machine. Containerize sample web applications using Docker to understand isolated software environments.
- Build: Launch a small cloud environment using free-tier services on popular cloud providers. Connect Prometheus and Grafana to visualize your server resource statistics on live charts.
- Test: Simulate outages by stopping key services intentionally to test your team alerts. Verify whether your monitoring stack detects failures quickly and accurately.
- Improve: Automate your manual troubleshooting steps using infrastructure code and continuous integration pipelines. Review your personal lab errors to build self-healing capabilities into your setups.
Frequently Asked Questions
1. Which primary responsibilities define the daily schedule of an SRE Engineer?
Production specialists monitor system performance metrics, write automation scripts, and manage live service interruptions. They review system health dashboards to isolate anomalies before users file complaints. They also collaborate with developers to ensure that incoming software updates meet strict stability standards. When high-priority outages strike, they organize the recovery response and study the event afterward to harden the network.
2. Can someone without operational experience enter the reliability engineering field?
Curious learners from various technical backgrounds can master reliability engineering through disciplined study. You can start by building a strong foundation in basic Linux administration, shell scripting, and core networking. After mastering these basics, experiment with container tools and cloud environments at home. Real-world laboratory projects help you develop practical operational skills faster than reading pure theory alone.
3. How do standard DevOps methodologies differ from site reliability practices?
DevOps defines an organizational philosophy that encourages software developers and operations teams to work together. Site Reliability Engineering delivers the concrete engineering blueprint that puts those collaborative ideas into practice. DevOps focuses heavily on rapid feature delivery, while reliability engineering safeguards live production stability. Both movements work hand in hand to help engineering organizations ship software safely without breaking active services.
4. Why do distributed software architectures require error budgets?
An error budget defines the acceptable margin of operational imperfection that an application can experience over time. It prevents disputes between feature developers who want rapid releases and operations staff who want absolute stability. When a service retains plenty of budget, developers can ship risky new updates quickly. If outages consume the budget, the team shifts focus toward resolving bugs and hardening infrastructure.
5. Which technical tools should an aspiring reliability engineer explore first?
Beginners should first master the Linux terminal, Git version control, and basic Bash scripting. Next, explore Docker to learn how modern containerization isolates running software processes from underlying host machines. Then, configure Prometheus and Grafana to learn how modern stacks collect, evaluate, and display operational metrics. Finally, study Terraform to understand how declarative code can build complete cloud environments automatically.
6. Does a successful career in reliability engineering demand software coding skills?
Reliability specialists write functional code daily to eliminate repetitive manual administration tasks across large server fleets. You do not need to create intricate commercial applications or user interfaces from scratch. However, you must write clean, reliable scripts in modern languages like Python, Go, or Bash. These programs automate daily deployments, configure alerts, query diagnostic logs, and restore crashed instances automatically.
7. What happens during a standard post-incident analysis meeting?
Following a major system disruption, the engineering team gathers to analyze the incident timeline thoroughly. The participants maintain a blame-free atmosphere, focusing entirely on systemic vulnerabilities rather than pointing fingers at individuals. The engineers investigate why the failure happened, why detection lagged, and how the team resolved the issue. Finally, they assign concrete tasks to prevent identical disruptions from recurring.
8. What core difference distinguishes monitoring from comprehensive observability?
Monitoring tracks predefined system metrics to notify you when specific components fail or slow down. Observability allows engineers to infer internal system health by analyzing outputs such as traces, metrics, and logs. While simple monitoring tells you that a service broke, observability explains why the unexpected failure occurred inside complex distributed systems. Both methods help engineers troubleshoot modern multi-tiered cloud applications swiftly.
9. How would you explain a Service Level Indicator to a newcomer?
A Service Level Indicator represents a concrete, real-time data point that gauges operational performance directly. For instance, it tracks the exact percentage of website requests that return successful responses within two seconds. Think of an indicator as a digital speedometer that displays the immediate velocity of your software. Engineers use this accurate metric to evaluate whether systems satisfy end-user requirements.
10. How does a Service Level Objective guide an engineering department?
A Service Level Objective specifies the exact target threshold that an engineering squad aims to achieve. It defines the formal boundary between acceptable system performance and unacceptable platform degradation over a fixed timeframe. For example, a team might set an objective that guarantees 99.9 percent of page loads finish smoothly. This clear target helps engineers balance feature innovation against critical system maintenance.
11. Why do enterprise corporations invest heavily in dedicated reliability units?
Modern businesses suffer enormous financial penalties and brand damage whenever critical transaction platforms crash unexpectedly. Frustrated consumers quickly abandon unreliable online services in favor of dependable competitors with better track records. Dedicated engineers protect revenue streams by neutralizing infrastructure vulnerabilities before external users feel any impact. Their automated architectures ensure that enterprise platforms scale effortlessly during massive customer purchasing events.
12. In what ways does programmatic automation transform daily engineering operations?
Automation shifts repetitive, error-prone tasks away from human operators and places them onto fast, predictable machines. Manual intervention during stressful emergencies often introduces typing blunders that worsen existing platform outages. By running proven, tested scripts, organizations execute complex disaster recovery workflows smoothly and accurately. This high operational velocity frees up valuable engineering time for strategic software design and system optimization.
Conclusion
Every successful digital platform depends on robust infrastructure, continuous monitoring, and automated incident response routines. Dedicated engineers eliminate repetitive administrative toil and guard complex server fleets against unpredictable software failures. Whenever major disruptions occur, technical teams analyze the evidence objectively and implement permanent architectural improvements. Platforms like SRESchool.in provide an organized curriculum that prepares aspiring technologists for modern cloud operations. Mastering these fundamental engineering skills gives you a clear understanding of scalable distributed systems. Dive into simple Linux terminal commands and automated scripting exercises today to begin building resilient infrastructure.
