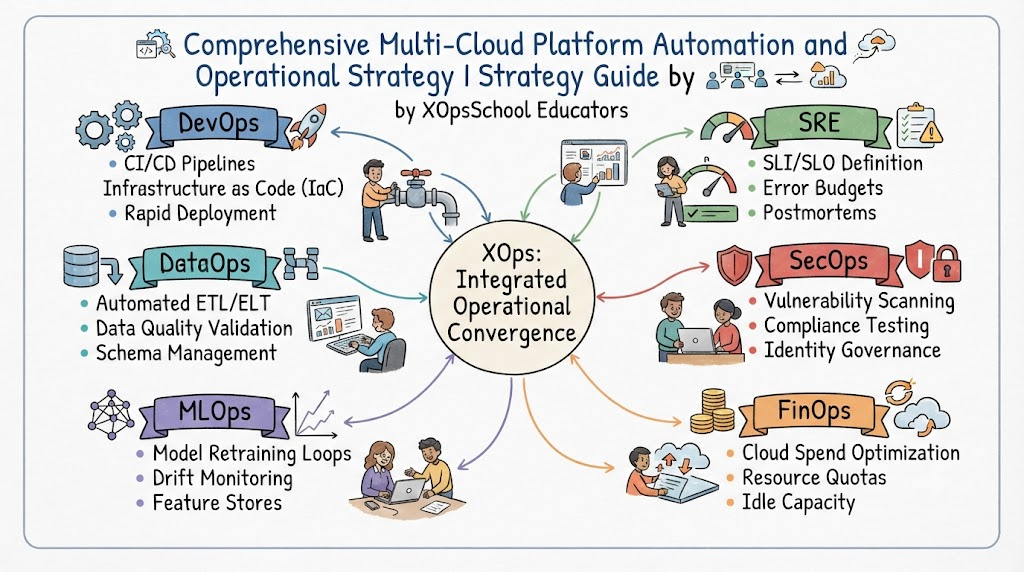
Modern enterprise software systems are evolving into deeply interconnected digital platforms where standalone operational teams can no longer function in isolated silos. High-velocity releases now require continuous alignment between software delivery, massive data workloads, machine learning lifecycle management, and intelligent system telemetry. Consequently, technical teams face mounting pressure to break down fragmented departmental walls and unify their delivery strategies under a single cohesive practice. This overarching necessity has led forward-thinking technical leaders to embrace XOpsSchool, establishing modern operational methodologies as the essential foundation for scalable systems. By functioning as an integrated operational philosophy, this broader mindset links infrastructure automation, data engineering, model maintenance, and artificial intelligence into a resilient operational lifecycle that guarantees system stability across distributed architectures.
What Is XOps?
At its technical core, the “X” in this emerging paradigm represents a flexible operational variable that stands for any core technology discipline requiring continuous lifecycle management, such as development, data, machine learning, security, or financial governance. Rather than treating each discipline as a disconnected set of practices, this umbrella methodology integrates delivery cadences, operational controls, and telemetry across the entire enterprise stack. Consider a modern dynamic e-commerce recommendation system: software developers update the core application through continuous integration pipelines, data engineers process incoming customer interaction streams, machine learning specialists update product prediction models, security teams scan container dependencies, and site reliability engineers monitor service health. When these operational functions collaborate through unified feedback loops, automated failure gates, and comprehensive observability, the organization achieves resilient, high-speed delivery without painful handoff delays or critical operational blind spots.
What Does XOps Include?
This holistic ecosystem brings together several specialized operational functions to create a synchronized technical foundation for distributed enterprise software platforms. Development operations delivers continuous software deployments, while data operations secures dependable streaming and batch pipelines. Machine learning operations automates continuous training and production model hosting, whereas artificial intelligence operations processes massive infrastructure telemetry through intelligent anomaly detection. Simultaneously, security operations embeds defensive policies into delivery pipelines, financial operations regulates cloud resource costs, site reliability engineering guards service level objectives, infrastructure operations provisions underlying hardware networks, and platform engineering constructs internal developer platforms. When interconnected, these distinct specializations eliminate disjointed workflows and align system resilience directly with end-to-end organizational software delivery goals.
| XOps Discipline | Primary Focus | Typical Responsibilities |
| DevOps | Software Delivery Velocity | Building CI/CD pipelines, container orchestration, Git automation, and automated deployment management. |
| DataOps | Data Quality & Pipeline Velocity | Orchestrating distributed pipelines, validating schemas, tracking lineage, and ensuring data observability. |
| MLOps | Model Lifecycle Automation | Versioning artifacts, managing automated retraining, deploying inference models, and tracking statistical drift. |
| AIOps | Intelligent Incident Detection | Correlating telemetry events, discovering systemic anomalies, reducing alert noise, and automating incident triage. |
| SecOps | Continuous System Protection | Automating vulnerability scans, managing credentials, enforcing runtime security policies, and maintaining audit compliance. |
| FinOps | Cloud Cost Governance | Tracking resource expenditure, optimizing cloud commitments, allocating operational budgets, and reducing infrastructure waste. |
| SRE | Service Availability & Resilience | Managing error budgets, defining service level objectives, optimizing latency, and conducting blameless postmortems. |
| InfraOps | Base Infrastructure Stability | Managing bare-metal servers, hypervisors, network routing, storage configurations, and low-level system resources. |
| Platform Engineering | Internal Developer Platforms | Building reusable infrastructure templates, standardizing developer portals, and curating golden development paths. |
What Is XOpsSchool?
Engineers and operations specialists seeking structured technical enrichment can utilize specialized platforms that demystify multi-disciplinary operational practices across complex environments. The core mission of this educational hub focuses on explaining interconnected concepts across containerization, declarative infrastructure configurations, continuous delivery mechanisms, data pipeline validation, and algorithmic incident management. Through step-by-step guides, architecture reviews, and hands-on operational analyses, technology professionals can dissect real-world production challenges and understand how these specialized disciplines integrate within modern distributed systems. By providing detailed breakdowns of modern delivery toolchains and architectural patterns, the platform equips technical learners with the foundational understanding required to design resilient, highly automated cloud-native infrastructures.
Why Is XOps Important?
Modern cloud-native systems rely heavily on microservice patterns, containerized deployments, and distributed data layers, which introduces substantial architectural friction when individual operational departments manage infrastructure in complete isolation. Without a unified operational strategy, organizations frequently struggle with inconsistent pipeline automations, security verification oversights, unchecked cloud infrastructure spending, and delayed incident resolutions caused by fragmented monitoring tools. When automated data pipelines fail or production machine learning models encounter unseen drift, standard infrastructure tools cannot pinpoint the root failure alone. Adopting an interconnected operational philosophy bridges these disjointed gaps by applying automated validation, standardized governance, and shared telemetry across the complete software delivery lifecycle, giving platform teams absolute visibility and reliable system performance.
Why Choose XOps Training?
Broadening technical horizons through a structured multidisciplinary program helps software engineers, system administrators, and infrastructure operators evolve beyond narrow tool-centric routines. Gaining proficiency across multiple operational domains allows technical professionals to design end-to-end automation strategies, evaluate complex architectural trade-offs, and implement dependable cloud-native practices across diverse environments. As modern engineering teams seek platform specialists capable of collaborating across development, security, data pipelines, and intelligent alerting platforms, broad operational fluency enhances team-wide problem-solving and systemic resilience. By understanding how telemetry, declarative automation, and reliability engineering align across different technology stacks, engineers can proactively eliminate bottlenecks, maintain stable release cadences, and build dependable operational frameworks.
How Does XOps Training Work in Practice?
Mastering complex cross-domain operations requires a systematic, hands-on learning trajectory that begins with core Linux systems, network protocols, shell scripting, and distributed Git workflows before progressing into container runtimes and automated continuous integration pipelines. Once developers grasp container orchestration with Kubernetes, declarative infrastructure provisioning using Terraform, and cloud-native networking, they integrate enterprise observability frameworks, automated policy enforcement, and proactive chaos engineering tests. From that stable foundation, learners incorporate modern data pipeline orchestration, automated machine learning lifecycle deployments, and intelligent operational monitoring tools for automated anomaly remediation. This technical journey emphasizes production-ready labs, real-world deployment challenges, and systematic debugging exercises, ensuring that engineers master robust, fault-tolerant patterns across interconnected technical environments.
XOps Certification: What Should You Look For?
When evaluating a structured operational certification, technical professionals must prioritize rigorous curricula that prioritize practical operational tasks and production scenarios over theoretical trivia. A comprehensive validation standard should assess real-world capabilities, including provisioning declarative cloud infrastructure, configuring secure Kubernetes clusters, establishing continuous delivery pipelines, and configuring centralized observability stacks. Furthermore, strong assessments incorporate advanced modules covering data pipeline validation, machine learning deployment workflows, and automated incident response correlation. While a credible certification demonstrates dedication to structured learning and confirms mastery of core operational techniques, engineers must always remember that formal credentials support, but never replace, genuine hands-on troubleshooting experience and deep architectural problem-solving capabilities.
XOps Tools: Understanding the Technology Stack
Modern cross-functional operations relies on an adaptable ecosystem of specialized tools designed to work collectively across every layer of the delivery lifecycle rather than depending on a single monolithic platform. Organizations integrate distinct tools for source tracking, container orchestration, policy compliance, declarative infrastructure provisioning, and distributed metrics aggregation to form dependable automation workflows. Selecting the right combination of tools ensures seamless data movement, consistent configuration state, automated testing, and comprehensive system visibility throughout the application lifecycle.
| Operational Area | Example Tools | Practical Purpose |
| Source Control & GitOps | Git, GitHub, GitLab, Argo CD | Managing declarative version control repositories and synchronizing automated state directly into target clusters. |
| CI/CD Automation | Jenkins, GitHub Actions, GitLab CI | Automating code build processes, running integration test suites, and triggering production deployments. |
| Containerization | Docker, Podman, containerd | Packaging application services with operational dependencies into lightweight, isolated runtime containers. |
| Container Orchestration | Kubernetes, Red Hat OpenShift | Managing container scheduling, automated scaling, internal service discovery, and zero-downtime rolling updates. |
| Infrastructure as Code | Terraform, OpenTofu, Pulumi | Provisioning and managing repeatable cloud infrastructure resources using declarative configuration files. |
| Configuration Management | Ansible, Puppet, Chef | Automating operating system package installation, configuration compliance, and routine operational maintenance. |
| Secrets Management | HashiCorp Vault, AWS Secrets Manager | Encrypting, storing, and rotating API keys, database credentials, and operational tokens safely across pipelines. |
| Metrics Observability | Prometheus, Grafana, Datadog | Scraping real-time system metrics, building operational dashboards, and visualizing cluster performance targets. |
| Centralized Logging | Elastic Stack (ELK), Fluentd, Splunk | Ingesting, parsing, and searching high-volume distributed logs to facilitate rapid system troubleshooting. |
| AIOps & Incident Correlation | Dynatrace, BigPanda, Moogsoft | Applying algorithmic pattern recognition to correlate incoming alerts and accelerate root-cause analysis. |
DevOps Training as the Foundation of XOps
Establishing a solid foundation in traditional software delivery methodologies is an absolute prerequisite before branching out into advanced operational practices such as data pipeline automation or machine learning hosting. Core development operations concepts, including continuous integration pipelines, Git branching strategies, infrastructure as code, container runtimes, and baseline telemetry, represent the core framework that sustains all other operational branches. Without mastering automated testing, declarative provisioning, and scalable Kubernetes administration, engineers cannot guarantee the underlying resilience required by complex data pipelines or sensitive inference models. Gaining deep operational expertise across core development operations ensures that engineers possess the critical automation mindset and architectural hygiene needed to manage complex technical platforms effectively.
AIOps Training: Adding Intelligence to Operations
Intelligent operations leverages machine learning models to analyze high-volume telemetry streams, filter out redundant operational alerts, and accelerate root-cause identification during critical production outages. Modern distributed architectures generate massive volumes of logs, traces, and metrics that easily overwhelm human engineering teams during complex cascading system failures. By employing automated anomaly detection, dynamic performance thresholding, and automated event correlation, intelligent operational engines pinpoint cascading infrastructure failures and can initiate automated remediation scripts before users notice performance degradation. However, technical teams must recognize that algorithmic operations tools depend entirely on clean, high-fidelity metrics and consistent logging formats; low-quality underlying data will inevitably produce misleading correlations and erratic automated operational decisions.
MLOps Training: Taking Machine Learning Into Production
Transitioning predictive artificial intelligence algorithms from experimental notebooks into stable, high-availability production environments demands robust continuous delivery patterns adapted for model lifecycles. Machine learning operations bridges this gap by managing continuous model testing, artifact versioning, automated containerized inference hosting, and strict resource isolation across GPU-accelerated computing clusters. Unlike standard software services, production machine learning applications require continuous operational monitoring for data drift and concept degradation as real-world input patterns deviate from original training distributions. By connecting traditional release automation with specialized model registries, automated validation tests, and dynamic retraining pipelines, operational teams ensure that statistical models remain highly accurate, dependable, and resilient under fluctuating production workloads.
DataOps Training: Making Data Operations Reliable
Treating data movement and transformation with the same engineering rigor applied to software delivery ensures that analytical pipelines and production data lakes remain consistently available, validated, and performant. Modern data operations establishes declarative orchestration pipelines that automatically run unit validations, track complete schema lineage, verify data integrity, and alert platform engineers to ingestion anomalies before downstream consumers are impacted. For example, when an upstream transactional database introduces a breaking schema alteration, an automated data delivery framework halts processing, alerts maintainers, and isolates malformed payloads rather than corrupting central analytical repositories. By enforcing version-controlled pipeline definitions, automated testing, and comprehensive data observability, organizations drastically reduce manual troubleshooting and provide reliable data streams for business-critical decision systems.
Real-Life Scenarios / Experiences
- A high-traffic payment processing platform encountered cascading failures when a minor database connection pool leak went unnoticed until the central service stopped responding; implementing automated telemetry correlation pinpointed the connection drop in real time and triggered an automatic rolling container restart before any user transactions timed out.
- An enterprise customer recommendation engine began generating inaccurate purchase suggestions due to unmonitored statistical feature drift in customer behavior; establishing automated machine learning monitoring pipelines detected the distribution variance, initiated automated model retraining, and deployed the updated model weights without manual engineering intervention.
- A distributed streaming analytics pipeline suffered silent data corruption when an upstream source modified an unannounced payload field; implementing continuous data validation gates immediately halted pipeline execution, isolated the non-compliant batch to a dead-letter queue, and preserved analytical warehouse integrity while notifying maintainers.
- A rapidly expanding software team faced unpredictable cloud hosting bills because temporary test environments were regularly abandoned after feature testing; configuring automated financial policy enforcement tools scanned declarative infrastructure templates, flagged unallocated cloud instances, and automatically terminated orphaned resources to maintain strict cost predictability.
Common Mistakes to Avoid When Choosing Learning Resources
- Prioritizing purely theoretical reading materials and multiple-choice quizzes while failing to verify whether the learning program includes dedicated, hands-on terminal labs and production-grade architectures.
- Choosing instructional programs that restrict training exclusively to a single vendor’s cloud ecosystem without demonstrating how to orchestrate hybrid, multi-cloud, or portable open-source operational toolchains.
- Focusing entirely on basic deployment scripts while neglecting deep system observability, centralized logging setups, distributed tracing, and real-time operational troubleshooting methodologies.
- Overlooking foundational security and governance concepts, such as role-based access controls, automated secrets rotation, vulnerability image scanning, and automated compliance policies within deployment pipelines.
- Attempting to master complex operational domains like machine learning or algorithmic event correlation before establishing core proficiency in Linux commands, networking, Git workflows, and container runtimes.
- Relying exclusively on introductory tutorials that build clean environments from scratch while ignoring how to manage, maintain, and refactor complex legacy technical debt in real-world systems.
- Assuming that obtaining a paper certification alone guarantees operational competence without creating a public portfolio of version-controlled infrastructure scripts, deployment pipelines, and post-incident analyses.
- Enrolling in unstructured courses that fail to explain how individual technical disciplines interconnect, leaving learners with fragmented skills rather than a unified architectural perspective.
How XOpsSchool Can Support the Learning Journey
Deepening cross-functional engineering skills requires consistent access to well-structured, technically sound documentation and clear architectural walk-throughs that bridge multiple technical specializations. By exploring detailed guides on container orchestration, infrastructure automation, Git-based release workflows, distributed tracing, and data pipeline observability, engineers can learn to coordinate diverse operational toolsets effectively. Step-by-step technical analyses help platform administrators understand how to design dependable continuous delivery pipelines, construct automated testing frameworks, and integrate intelligent alerting engines into production clusters. Utilizing comprehensive, industry-aligned learning content allows technical practitioners to cultivate the cross-disciplinary problem-solving capabilities necessary to design, maintain, and troubleshoot resilient enterprise software ecosystems with complete confidence.
How to Get the Most From an XOps Course
Maximizing the value of an advanced operational training program requires active, inquiry-driven experimentation rather than passive video consumption. Engineers should embrace a rigorous cycle: construct an architecture, break its components intentionally, analyze the resulting telemetry, resolve the failure, document root causes, automate remediation scripts, and track system latency impacts. For instance, after deploying a production-style Kubernetes cluster, deliberately inject network latency, terminate essential pods unexpectedly, or corrupt database credentials to observe how health checks respond under pressure. Documenting how the infrastructure reacts to deliberate chaos and automating recovery procedures deepens your practical engineering instincts. This hands-on, problem-solving methodology transforms theoretical knowledge into deep production troubleshooting expertise, ensuring that you can calmly stabilize distributed enterprise architectures during high-stress operational outages.
Frequently Asked Questions
1. What does the term XOps actually mean in modern IT?
The term represents an expansive operational framework where the variable “X” stands for any essential technical practice, such as development, security, data pipelines, or machine learning. Rather than managing these teams in disconnected silos, this framework unifies their delivery cycles, automation patterns, and system telemetry under a cohesive engineering model to ensure operational resilience.
2. How is this multidisciplinary approach different from traditional DevOps?
Traditional software delivery practices primarily bridge the gap between software development and IT infrastructure through automated deployment pipelines. This broader approach expands those core principles across data pipelines, machine learning lifecycles, financial cost governance, and automated incident correlation, ensuring complete operational alignment across modern multi-faceted enterprise systems.
3. Do I need to master software development before learning these operational concepts?
You do not need to be an expert software developer, but you must understand basic coding logic, shell scripting, and application structures. Basic scripting enables you to automate infrastructure tasks, configure deployment pipelines, inspect service configurations, and diagnose unexpected application runtime exceptions within production container environments.
4. Which foundational technical skills should I learn first?
Begin by mastering fundamental Linux system commands, core networking protocols, version control using Git, and basic bash or Python scripting. Once comfortable with these fundamentals, progress to container runtimes, declarative infrastructure tools, and automated deployment pipelines before tackling advanced data, machine learning, or automated operational monitoring platforms.
5. Why is telemetry and observability so critical across interconnected operations?
Unified observability provides continuous visibility into application traces, infrastructure metrics, and structured log events across distributed environments. Without centralized telemetry, engineering teams cannot trace intermittent microservice latency, locate data pipeline corruption, detect statistical model drift, or accurately diagnose cascading multi-system production failures during severe service outages.
6. Can an engineer specialize in one discipline while practicing this framework?
Yes, technical professionals frequently specialize in a primary domain, such as data operations, security, or site reliability engineering, while maintaining broad cross-functional literacy. Understanding how your specialty interacts with container orchestration, cloud networking, and continuous delivery allows you to build better integrations and collaborate effectively across engineering teams.
7. What is the role of machine learning in intelligent operations?
Intelligent operational tools apply algorithmic pattern recognition to high-volume telemetry streams to filter repetitive alert noise, identify anomalous performance spikes, and accelerate root-cause triage. These automated systems help platform teams isolate cascading microservice failures rapidly and initiate automated recovery workflows before end users experience degraded application performance.
8. Does choosing this broad operational path require learning every single tool?
No, you do not need to master every available tool on the market. Instead, focus on understanding fundamental architectural patterns, such as declarative configurations, container orchestration, Git-driven deployments, and structured telemetry. Once you grasp these fundamental patterns, adapting to specific vendor tools or open-source alternatives becomes straightforward.
9. How does data operations integrate with standard delivery pipelines?
Data delivery practices apply version control, automated testing, and continuous deployment disciplines to data schemas, analytical pipelines, and storage lakes. This integration ensures that schema modifications are validated through automated test gates, preventing upstream structural changes from corrupting downstream analytical databases and operational business dashboards.
10. What makes an operational certification genuinely valuable?
A valuable certification features comprehensive, hands-on lab evaluations that test real-world implementation, troubleshooting, and architectural design rather than passive multiple-choice theory. It validates your ability to configure declarative infrastructure, stabilize unhealthy container clusters, secure deployment pipelines, and interpret live operational telemetry under realistic production constraints.
11. How do platform engineering teams support cross-functional operations?
Platform engineering teams design, build, and maintain internal developer platforms that package complex infrastructure, deployment pipelines, and monitoring tools into reusable self-service workflows. This infrastructure abstraction reduces cognitive load on product developers while ensuring consistent security policies, standardized deployments, and uniform telemetry throughout the entire organization.
12. How should beginners approach troubleshooting complex distributed environments?
Beginners should follow a methodical, evidence-based diagnostic process by checking system logs, reviewing service health endpoints, inspecting resource limits, and tracing network requests step-by-step. Avoid changing configurations blindly; instead, isolate the failing component, reproduce the error reliably, document your findings, and automate validation tests to prevent recurring incidents.
Conclusion
Embracing a comprehensive, multi-disciplinary operational mindset allows modern organizations to bridge historical engineering divides, align automated delivery pipelines, and maintain resilient cloud architectures across fast-paced production environments. By unifying software release automation, reliable data pipelines, machine learning lifecycles, and algorithmic telemetry monitoring into a shared operational philosophy, technology teams can eliminate delivery bottlenecks and build fault-tolerant systems. Developing cross-functional operational literacy empowers engineers to navigate complex cloud-native architectures with technical clarity, solve intricate systemic failures efficiently, and build scalable infrastructure platforms capable of supporting modern software delivery demands.
